01
The shift: from chat interface to product capability
The first wave of generative AI integrations often placed a chat panel beside an existing product. The stronger second wave embeds intelligence directly into a task: summarize a support case before handoff, transform a draft into a structured listing, extract fields from a document, explain an analytics anomaly, or propose the next safe action in a workflow.
This changes the engineering question. Instead of “Which model should we add?” ask “Which user decision becomes faster or better, what evidence is available, what may the system change, and how will we know the result is good?” The model is one component in that system—not the product and not the source of truth.
Mobile platforms now expose production paths for on-device generative tasks. Android documents Gemini Nano-backed ML Kit APIs and hybrid on-device/cloud choices; Apple exposes on-device Foundation Models with structured generation and tool calling. These capabilities make latency, privacy, offline behavior, and device eligibility first-class architecture constraints.[1][2]
Key takeaway
A valuable AI feature should have a crisp job, bounded authority, available evidence, and a non-AI path when intelligence is unavailable.
02
Choose the right execution plane
Use deterministic code for rules, arithmetic, permissions, pricing, validation, and irreversible state transitions. A language model should not decide a tax total, invent an inventory level, or bypass an authorization check. Deterministic code is cheaper, testable, and exact.
Use on-device models when the task is compact, latency-sensitive, privacy-sensitive, or should work offline: summarization, rewriting, classification, entity extraction, short translation, and lightweight image understanding are common candidates. The trade-off is a smaller context window, variable device eligibility, OS-dependent model versions, and less reasoning capacity. Apple explicitly recommends checking availability and designing a fallback because the model may be unsupported, disabled, or not ready.[1][2][6]
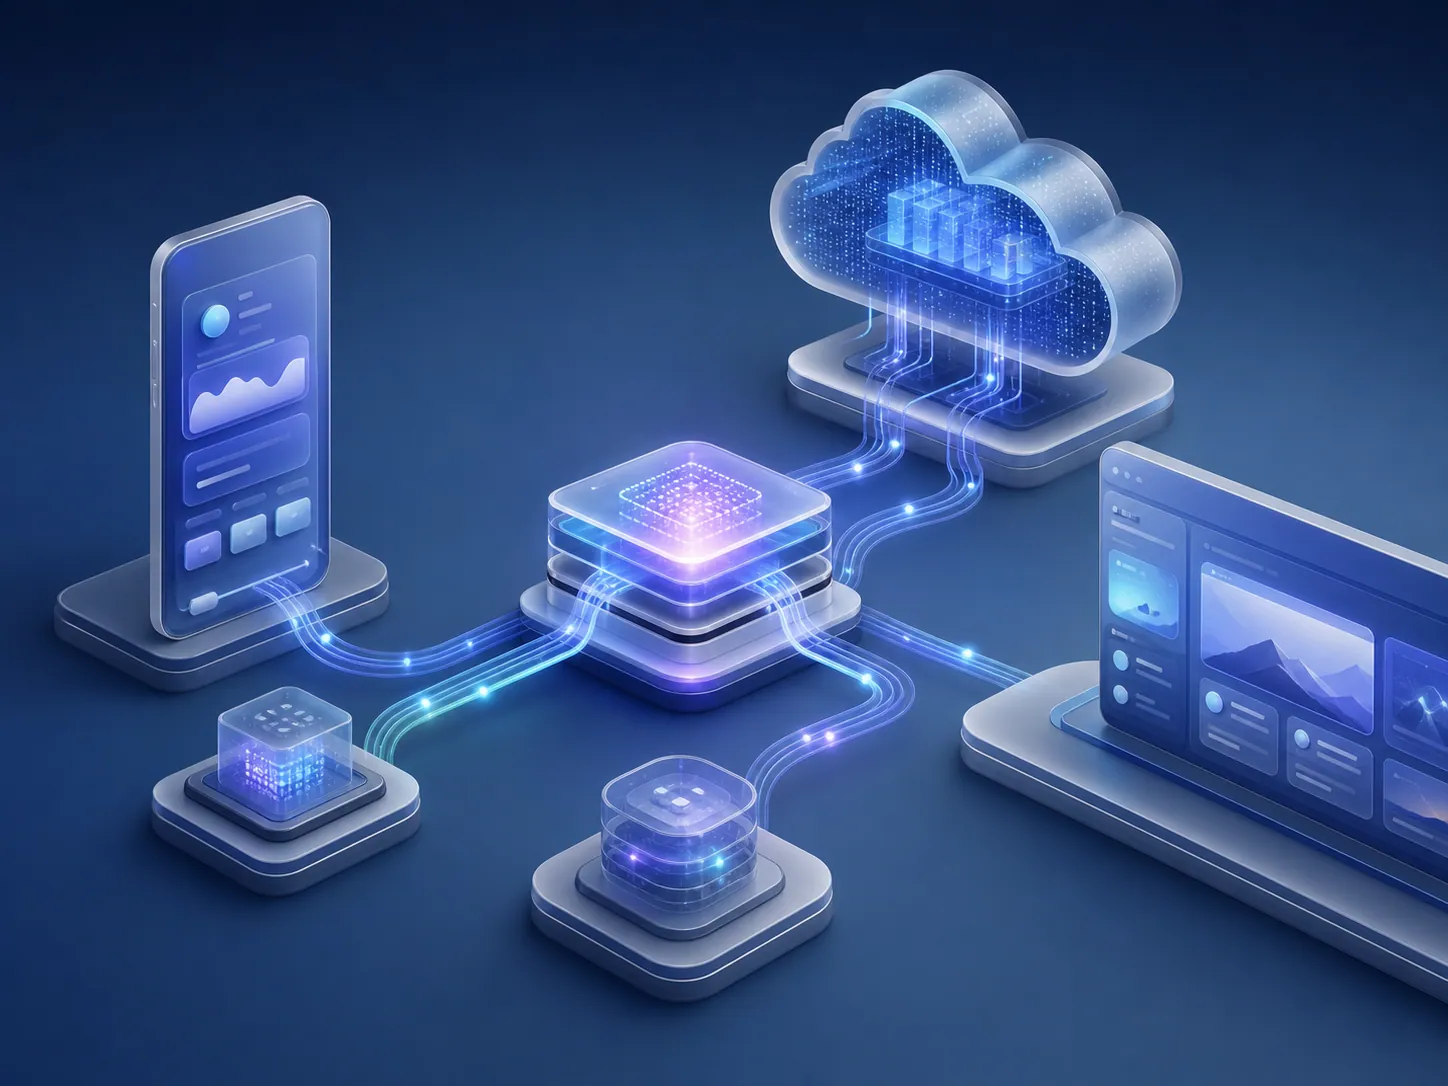
Use cloud models for deeper reasoning, large context, broad knowledge, cross-platform consistency, or expensive multimodal work. The trade-off is network latency, inference cost, regional availability, data-governance obligations, and provider dependency. A hybrid router can attempt a local task, fall back to a cloud capability with consent and policy checks, and finally offer a deterministic manual workflow.
if (task.isDeterministic) return rulesEngine.run(task);

if (deviceModel.available && task.fitsLocalLimits) {
  return localModel.run(task);
}

if (policy.allowsCloud(task.dataClass)) {
  return cloudModel.run(redact(task));
}

return manualFallback(task);
Key takeaway
Route by task, data sensitivity, latency, capability, cost, and failure mode—not by whichever model is newest.
03
Use a four-layer product architecture
The experience layer owns the visible interaction: input, streaming state, citations, undo, confirmation, and error recovery. It should never expose raw provider errors or make the entire interface wait when only one intelligent enhancement is pending.
The orchestration layer turns product intent into a bounded request. It selects a model, retrieves permitted context, sets time and token budgets, validates structured output, enforces tool policy, retries only safe transient failures, and records a trace. Keep provider-specific details behind this boundary so mobile and web clients share product rules.
The intelligence layer contains prompts, model adapters, retrieval, ranking, and domain-specific transformations. The trust layer contains identity, authorization, data classification, safety filters, audit logs, rate limits, and human approval. Keeping trust independent prevents a prompt or model update from silently changing permissions.
- Version prompts, schemas, tools, retrieval indexes, and model configurations together.
- Return typed domain objects, not prose that downstream code must guess how to parse.
- Put authorization inside the tool or service boundary, not only in the model instructions.
- Record model, prompt version, tool calls, latency, token use, and outcome for each trace.
04
Constrain output; isolate tools
Free-form text is appropriate when text is the final product. When software will consume the result, require a schema: an array of extracted entities, a proposed support action, a risk label with evidence, or a draft object with explicit optional fields. Validate the result with normal application code before it reaches storage or another service.
Tool calling extends a model from language generation into action, which also expands the risk surface. Expose the smallest possible tool set for the current task. Use narrow arguments, server-side authorization, idempotency keys for mutations, spend and quantity limits, and explicit approval before consequential actions. Never place a database client, shell, or broad internal API directly behind a model.
Treat retrieved documents, websites, emails, uploaded files, and tool responses as untrusted content. OWASP lists prompt injection and sensitive-information disclosure among the leading risks for generative-AI applications. Retrieval and fine-tuning can improve relevance, but they do not create an authorization boundary or eliminate injection.[4]
- Allow-list tools for each workflow rather than sharing a universal tool catalog.
- Separate read tools from mutation tools and require stronger confirmation for the latter.
- Sanitize rendered output and never execute model-produced markup or code by default.
- Limit recursion, tool-call count, elapsed time, tokens, and financial exposure.
Key takeaway
The model proposes; trusted application code validates, authorizes, and commits.
05
Design latency, uncertainty, and control into the UX
AI latency is variable. A strong interface acknowledges input immediately, streams partial output only when it helps, and lets the rest of the product remain usable. For short transformations, a stable skeleton may be calmer than a token stream. For a longer assistant response, streaming with meaningful section boundaries can reduce perceived wait.
Show the difference between a suggestion and a committed action. Provide edit, regenerate, undo, and “use original” paths. Cite source material when the answer depends on retrieval. If confidence is low or evidence conflicts, ask a focused question or hand the task back rather than filling the gap with fluent language.
Accessibility applies to intelligent states too. Announce completion without reading every streamed token through a screen reader, preserve focus, support reduced motion, and ensure generated labels or descriptions can be corrected. Users should be able to complete the core task without voice input or an AI-only control.
Key takeaway
Trust grows when the interface makes status, evidence, reversibility, and the boundary of AI authority visible.
06
Minimize context before maximizing intelligence
More context is not automatically better. Build a context contract for each feature: which fields are necessary, where they may be processed, how long they are retained, and which identities may access them. Redact secrets and irrelevant personal data before a cloud request. Prefer references or retrieved fragments over entire customer records.
On-device inference can improve privacy and offline behavior because inputs may remain local, but it does not remove product responsibility. Generated output can still reveal sensitive local data on screen, enter logs, or be passed to a cloud tool. Apply the same data classification to prompts, retrieved context, model output, traces, and feedback.
Use a documented risk process for consequential features. NIST’s Generative AI Profile extends its AI Risk Management Framework with actions for generative-AI risks across design, deployment, evaluation, and governance. The practical takeaway is to assign owners, define acceptable failure, test foreseeable misuse, and keep evidence that controls operate.[5]
- Do not train on customer content by default or imply that product usage equals consent.
- Separate operational traces from reusable evaluation datasets.
- Set retention periods and deletion behavior before launch.
- Review regional data-processing and age-related requirements with qualified counsel.
07
Ship evaluations with the feature
Traditional tests still cover schemas, permissions, routing, fallbacks, and tools. Model behavior needs an evaluation set: representative tasks, edge cases, adversarial inputs, multiple languages, and known failure examples. Score task success, groundedness, harmful behavior, format validity, latency, and cost. Human review remains valuable for nuanced quality, but it should use a consistent rubric.
Run the evaluation set whenever the prompt, model, retrieval index, tool description, or orchestration logic changes. In production, monitor acceptance, edit distance, undo rate, escalation rate, tool failures, safety interventions, latency percentiles, and cost per completed task. A lower token bill is not an improvement if users must redo the work.
Platform models can change with an OS update. Apple’s 2026 Foundation Models guidance specifically warns teams to test prompts against new system-model versions. Model drift is therefore not only a cloud-provider concern; mobile release testing needs AI regression coverage as well.[3]
Key takeaway
An AI feature without a repeatable evaluation set is a demo with production traffic.
08
A pragmatic implementation roadmap
Begin with one narrow, reversible workflow where the user can judge the answer. Establish a deterministic baseline and collect examples. Build the typed output contract and manual fallback before tuning prompts. Then add the smallest model capable of meeting the quality target.
Next, add evaluation and trust controls: a golden dataset, adversarial cases, authorization inside tools, data redaction, limits, traces, and an approval step for consequential actions. Pilot with a small cohort, review failures weekly, and expand only when quality and operational cost are stable.
The future is not one universal assistant. It is a portfolio of bounded intelligent capabilities, routed across device and cloud, embedded in familiar workflows, and governed like every other production system.
- Pick one task with clear value and a human-verifiable result.
- Define schema, fallback, data contract, and authority boundary.
- Create the evaluation set before optimizing the prompt.
- Pilot, observe real corrections, and scale by proven capability.
Research
Sources & further reading
This article was researched from standards bodies, platform documentation, and first-party engineering studies. Sources were reviewed for the publication and update dates shown above.
- 1Find the right AI/ML solution for your appAndroid DevelopersOfficial guidance for choosing on-device, cloud, custom, and hybrid AI on Android.
- 2Generating content and performing tasks with Foundation ModelsApple DeveloperCapabilities, availability checks, and fallback guidance for Apple’s on-device model.
- 3Foundation Models updatesApple DeveloperCurrent framework and system-model changes, including 2026 testing guidance.
- 4Top 10 for Large Language Model ApplicationsOWASPCurrent risk categories for generative-AI and LLM applications.
- 5Artificial Intelligence Risk Management Framework: Generative AI ProfileNISTA cross-sector framework for identifying and managing generative-AI risk.
- 6Prompting an on-device foundation modelApple DeveloperOfficial constraints and prompt-design advice for smaller on-device models.